Research
The world's best AI labs in 2026, leaderboard by leaderboard, and where Brazil stands
OpenAI, Anthropic and Google lead among model labs, with Z.ai, Moonshot, DeepSeek and Alibaba from China. Rogue, from Brazil, has the top published score on two agent tests and sits above the public leaderboard on the third.
Three public tests measure agents working on their own on long software and science tasks: Terminal-Bench 4.0, Terminal-Bench-Science 0.1 and DeepSWE v1.1. We gathered each lab's best result on each one, with the source of every number.
The table
| Lab | Country | Terminal-Bench 4.0 | TB-Science 0.1 | DeepSWE v1.1 |
|---|---|---|---|---|
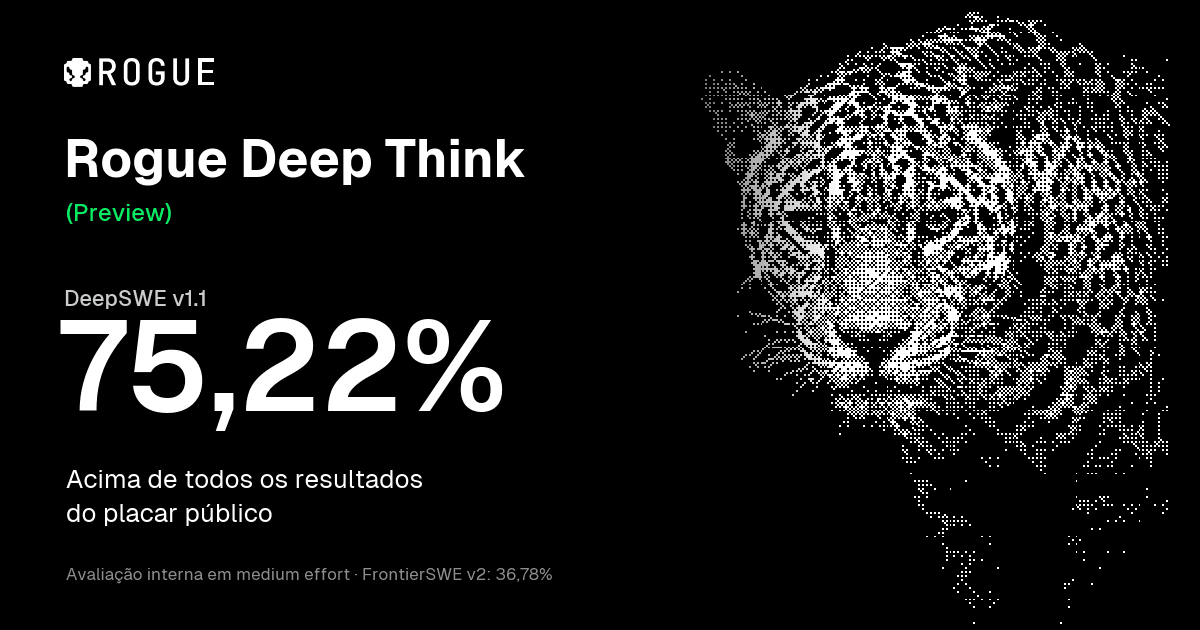
| Rogue | Brazil | 71.21%Rogue Constellation | 71.43%Rogue Constellation | 75.22%Rogue DeepThink Preview |
| OpenAI | US | 57.9%GPT-6 Astra | 63.3%GPT-6 Astra | 74.12%GPT-6 Astra |
| US | 57.4%Gemini 4 Argon | 57.6%Gemini 4 Argon | 73.83%Gemini 3.8 Flash | |
| Anthropic | US | 66.4%Claude Opus 5.5 | 61.9%Claude Opus 5.5 | 73.65%Claude Opus 5 |
| Z.ai | China | no result | no result | 68.96%GLM 5.3 |
| Moonshot AI | China | no result | no result | 68.51%Kimi K3 |
| xAI | US | no result | no result | 66.74%Grok 4.6 |
| DeepSeek | China | no result | no result | 62.83%DeepSeek V4 Pro |
| Alibaba | China | no result | no result | 57.46%Qwen 3.8 Max |
| Meta | US | no result | no result | 55%Muse Spark 1.2 |
Who leads
Among the labs that train the models, OpenAI leads the public DeepSWE leaderboard with 74.12% for GPT-6 Astra. Anthropic has 66.4% for Claude Opus 5.5 on Terminal-Bench 4.0, and Google is close to both, with 73.83% for Gemini 3.8 Flash on DeepSWE.
The Chinese labs come next. GLM 5.3 (Z.ai), Kimi K3 (Moonshot AI), DeepSeek V4 and Qwen 3.8 (Alibaba) sit between 57% and 69% on DeepSWE, close to xAI's Grok. Meta's Muse Spark 1.2 is on the leaderboard at 55%.
Brazil's result
Rogue has the top published score on Terminal-Bench 4.0 and Terminal-Bench-Science 0.1, and sits above the public DeepSWE v1.1 leaderboard. On Terminal-Bench 4.0, Rogue Constellation scored 71.21%, ahead of Claude Opus 5.5 (66.4%) and GPT-6 Astra (57.9%). On Terminal-Bench-Science 0.1 it scored 71.43%, against 63.3% for GPT-6 Astra. On DeepSWE v1.1, Rogue DeepThink Preview scored 75.22%, ahead of GPT-6 Astra (74.12%).
The result does not come from a bigger model. Rogue builds systems on top of frontier models. DeepThink builds on GLM 5.3, which alone scores 68.96% on DeepSWE and is the 5th lab in the table; with DeepThink, the same model reaches 75.22% and moves to 1st. Constellation, our flagship coding agent, orchestrates the best frontier models.
That is what puts Brazil in the same table: research on getting more out of the models that exist, measured on the leaderboards the labs themselves use.